No retraining.
Use just the CAD model to introduce a new object instead of collecting and labeling another object-specific dataset.
6D perception for robotics
Turn a CAD model into a
6D pose in seconds.
No image collection. No retraining.
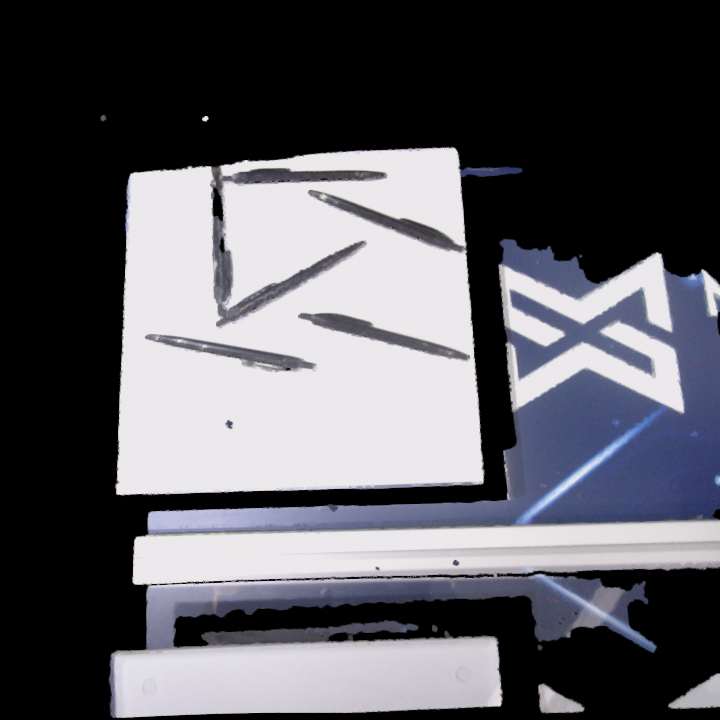
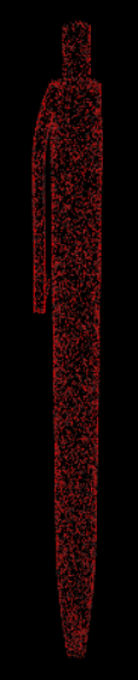 CAD MESH
xPerception matches a CAD model to live camera input and returns grasp-ready 6D object poses without image collection or retraining.
xPerception's vision
Every time a new part hits the line, the vision system has to be retrained.
That single step decides whether a small or custom batch is viable.
Use just the CAD model to introduce a new object instead of collecting and labeling another object-specific dataset.
Keep a consistent perception workflow across changing objects, cameras and robotic cells.
Made for environments where product variety is high and the number of instances per object can be low.
From CAD to grasp directly
It connects to your existing camera and robot workflow, localizes unseen parts, and provides the pose and configured grasp needed for picking.
Three steps, handled by the line operator directly. Upload the CAD, mark the grasp points, and press run.
No code, retraining, or reconfiguration for each new part.
Import the object's 3D model.
Zero training images, zero annotation.
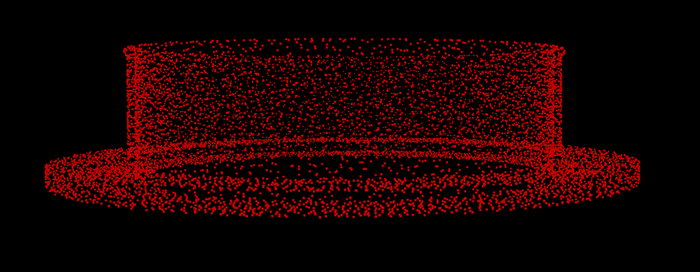
Choose your desired grasp points on the object CAD. The configuration blends to the CAD model.
xPerception finds the object, estimates its 6D pose and sends the configured grasp directly to the robotic workflow.
At Automatica 2025, xPerception picked randomly scattered, visually identical pens and aligned each for laser engraving, using only its CAD model and zero training data.
Live at the Peitian Robot booth · Integrated by Metaup srlWinner · BOP Challenge 2024
The core technology behind xPerception was recognized as the overall best method in both model-based tracks for unseen objects.
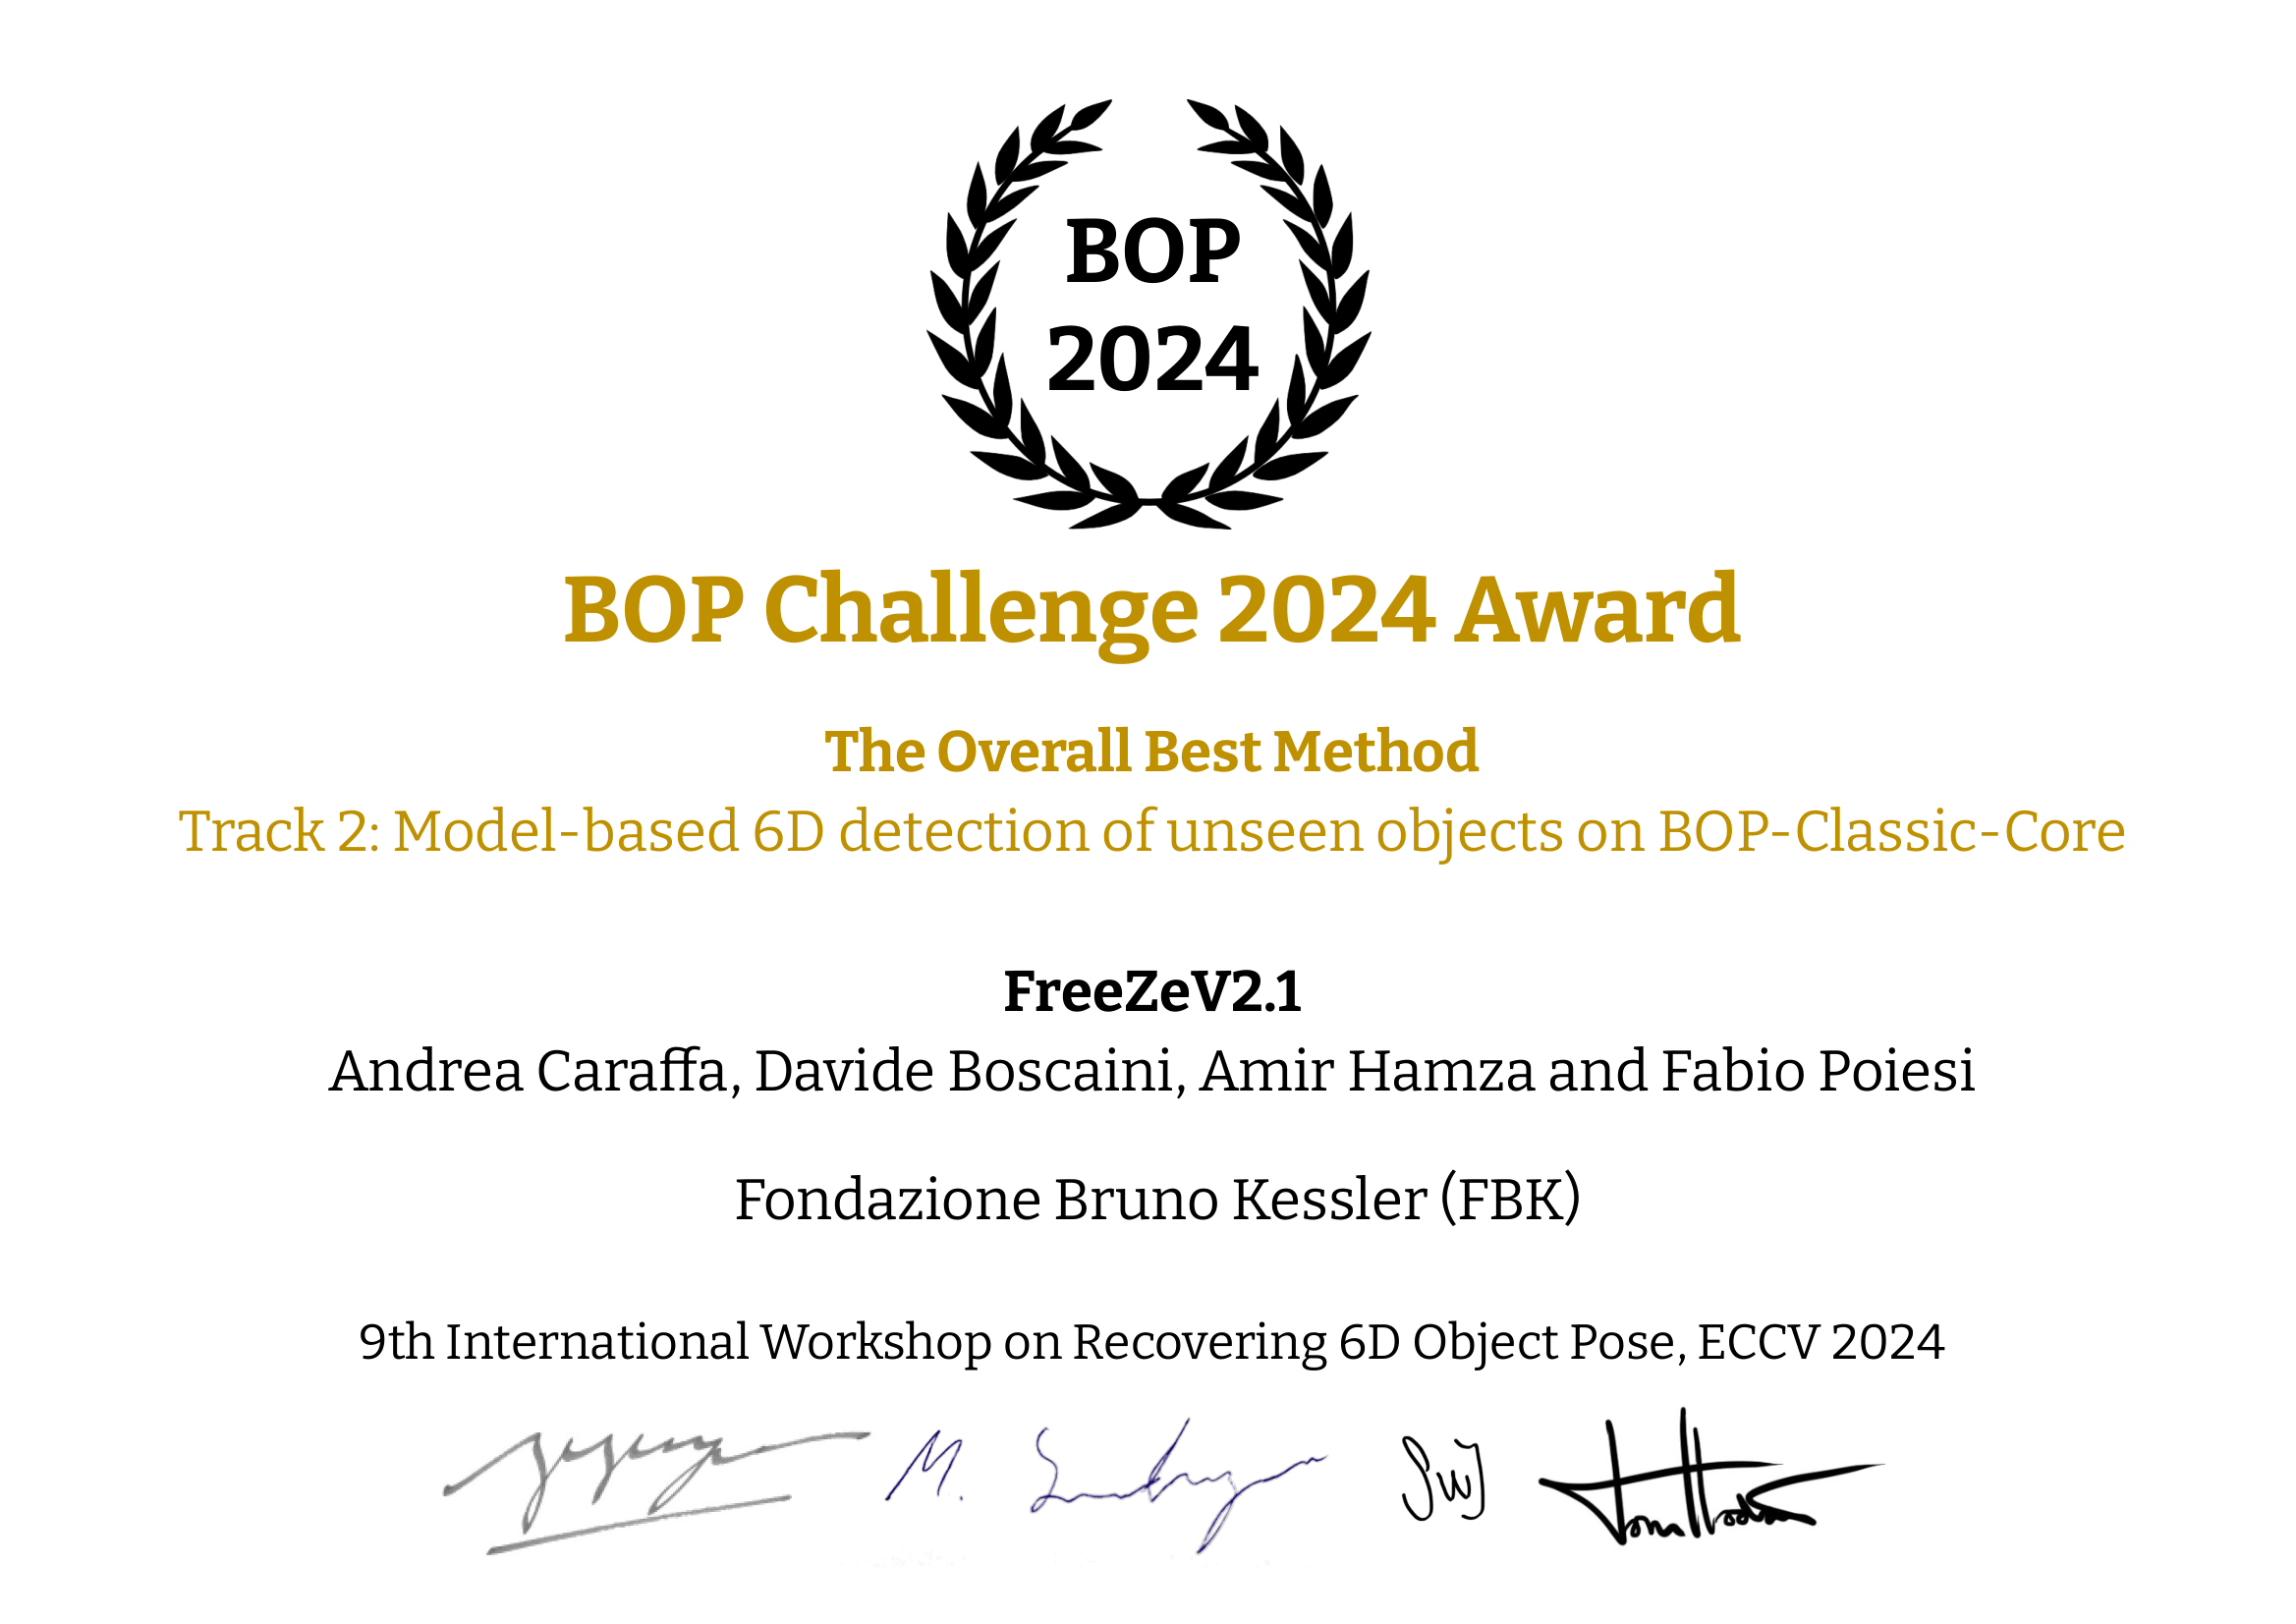
A. Caraffa, D. Boscaini, A. Hamza, F. Poiesi, “FreeZe: Training-free zero-shot 6D pose estimation with geometric and vision foundation models” ECCV 2024.
From the Technologies of Vision Lab
A spin-off of Fondazione Bruno Kessler in Trento, Italy, built by researchers working across computer vision, deep learning and robotics.
Computer Vision Engineer
First author of FreeZe, the zero-shot pose estimation algorithm at the core of xPerception, published at ECCV.
LinkedIn ↗
Computer Vision & Robotics Engineer
Works on language-driven robotic reasoning and grasping, taking xPerception beyond pose estimation toward full manipulation.
LinkedIn ↗
PhD · Head of TeV Lab
Leads the Technologies of Vision unit, with two decades of 3D vision and point-cloud registration research.
LinkedIn ↗How it started"xPerception started as a research question inside the lab, not a product brief: what is accurate 6D object pose estimation actually worth on a real production line? Chasing that question through years of 3D vision and robot-learning research, and the award-winning FreeZe algorithm it produced, turned into a technology validated on industrial hardware, and then into a company." Where it is going"Our ambition doesn't stop at pose estimation. We want xPerception to become the perceptual engine behind scalable, plug-and-play robotic automation, so that high-mix, low-volume manufacturing can run as efficiently as mass production always has."
Request a demo
Tell us about your line, objects and robotic setup. We'll show you a zero-shot grasp on your own parts.
We'll get back to you shortly.